High-throughput Contract Processing
Refactored the critical contract upload pipeline that handles high-volume financial workloads under strict SLAs. Owned the service end-to-end.
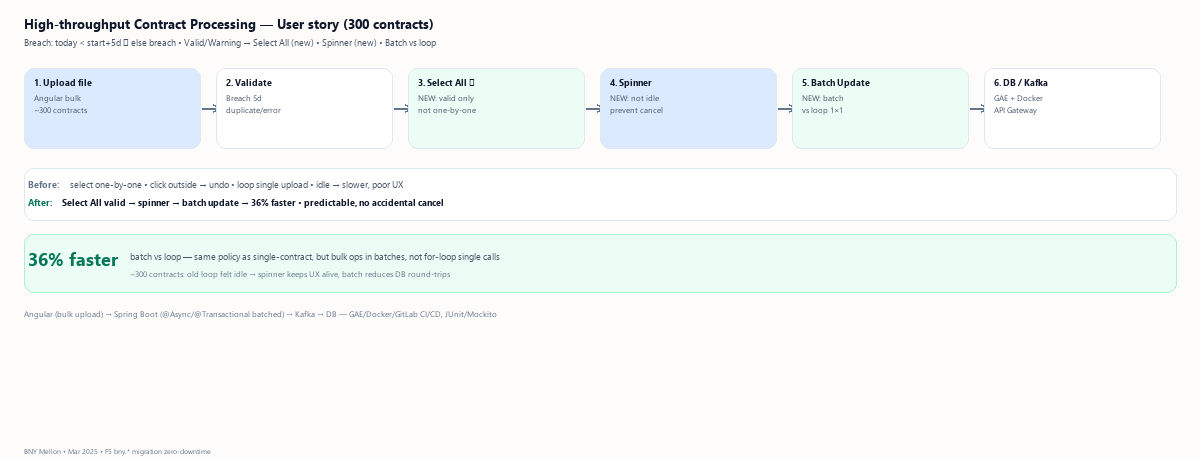
Contract uploads were slow and non-deterministic — large batches hit transaction timeouts, retries created duplicates, and SLAs slipped. The domain is banking: correctness and idempotency matter more than raw speed.
- Re-tuned transaction boundaries — short, batched
@Transactionalunits instead of one giant TX. - Parallelized with
@Async+ bounded queues — predictable throughput, no thread starvation. - Added idempotency keys + validation/anomaly detection — safe retries.
- Secured REST + Kafka via API Gateway / Manager (throttling, rate limiting, sandbox URLs).
- Deployed on Google App Engine with Docker + GitLab CI/CD, expanded JUnit/Mockito/API coverage for confidence.
Tuning @Async thread pools without starving Kafka consumers; keeping transactions short enough to avoid lock escalation but not so short that rollback cost spikes; and the *.bnymellon.* → *.bny.* URI migration with zero perceived downtime across F5 and assembly configs.
36% end-to-end reduction, predictable SLAs, zero-downtime migration, higher deployment confidence from expanded tests.
Valid patterns reused for DR/Kafka work on the same platform.
Role: Backend owner
Timeline: Mar 2025